
Building Scalable ETL Pipelines: A Guide for Data Engineers


Understanding ETL Pipelines
ETL, which stands for Extract, Transform, Load, is a critical process in data engineering. It involves extracting data from various sources, transforming it into a suitable format, and loading it into a destination system, usually a data warehouse. Building scalable ETL pipelines ensures that data processes can handle growing volumes without compromising performance.
Key Considerations for Scalability
When designing ETL pipelines, scalability should be at the forefront. A scalable pipeline can manage increased data loads efficiently. Here are some key considerations:
- Modular Design: Break down the pipeline into smaller, manageable components.
- Automation: Automate repetitive tasks to reduce manual intervention.
- Parallel Processing: Implement parallel processing to speed up data handling.
Choosing the Right Tools
Selecting the appropriate tools is crucial for building scalable ETL pipelines. Popular choices include Apache Spark, Apache Nifi, and Talend. These tools offer features that support high-volume data processing and transformation. Consider factors like ease of integration, community support, and cost when choosing your tools.
Implementing Data Transformation
Data transformation is a vital step in the ETL process, where raw data is converted into a useful format. This step often involves cleaning, normalizing, and enriching data. Implementing efficient transformation logic ensures data accuracy and quality. Consider using frameworks that support distributed processing to handle large datasets.
Monitoring and Maintenance
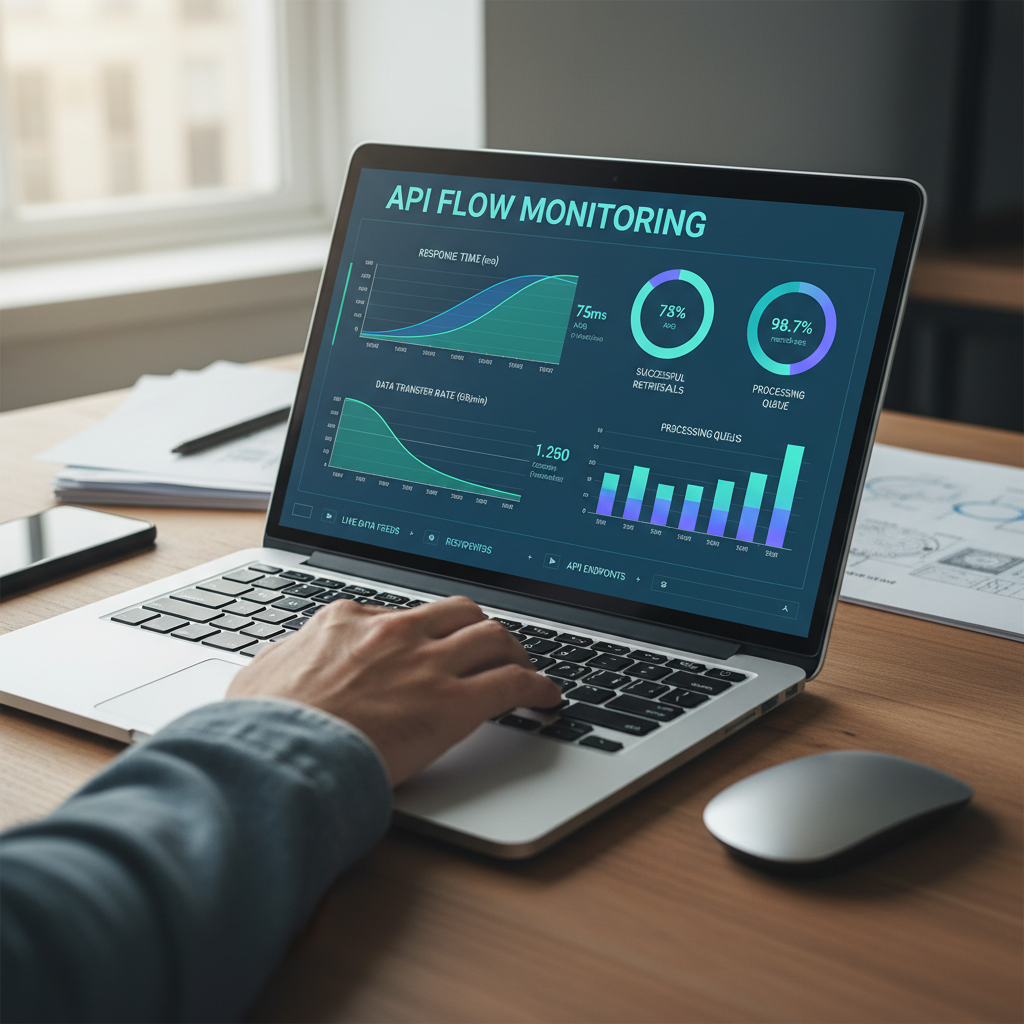
Regular monitoring and maintenance of ETL pipelines are essential to ensure smooth operations. Set up alerts to identify issues promptly and schedule routine maintenance to update systems and fix bugs. Using monitoring tools can help visualize data flows and detect bottlenecks.
Optimizing Performance
Performance optimization is key to a successful ETL pipeline. Start by identifying and resolving bottlenecks, such as slow data sources or inefficient transformations. Optimize queries and use indexing where possible to speed up data retrieval. Additionally, consider scaling resources dynamically to meet demand.
Ensuring Data Security
Data security must not be overlooked when building ETL pipelines. Implement encryption for data at rest and in transit. Control access to sensitive data with robust authentication and authorization mechanisms. Regular security audits can help identify vulnerabilities and protect data integrity.
Future-Proofing Your ETL Pipelines
As technology evolves, so should your ETL pipelines. Stay updated with the latest trends and tools in data engineering. Incorporate flexible designs that can adapt to new requirements and technologies. By future-proofing your pipelines, you ensure they remain effective and scalable as your business grows.